Rich, geo-targeted LLM insights
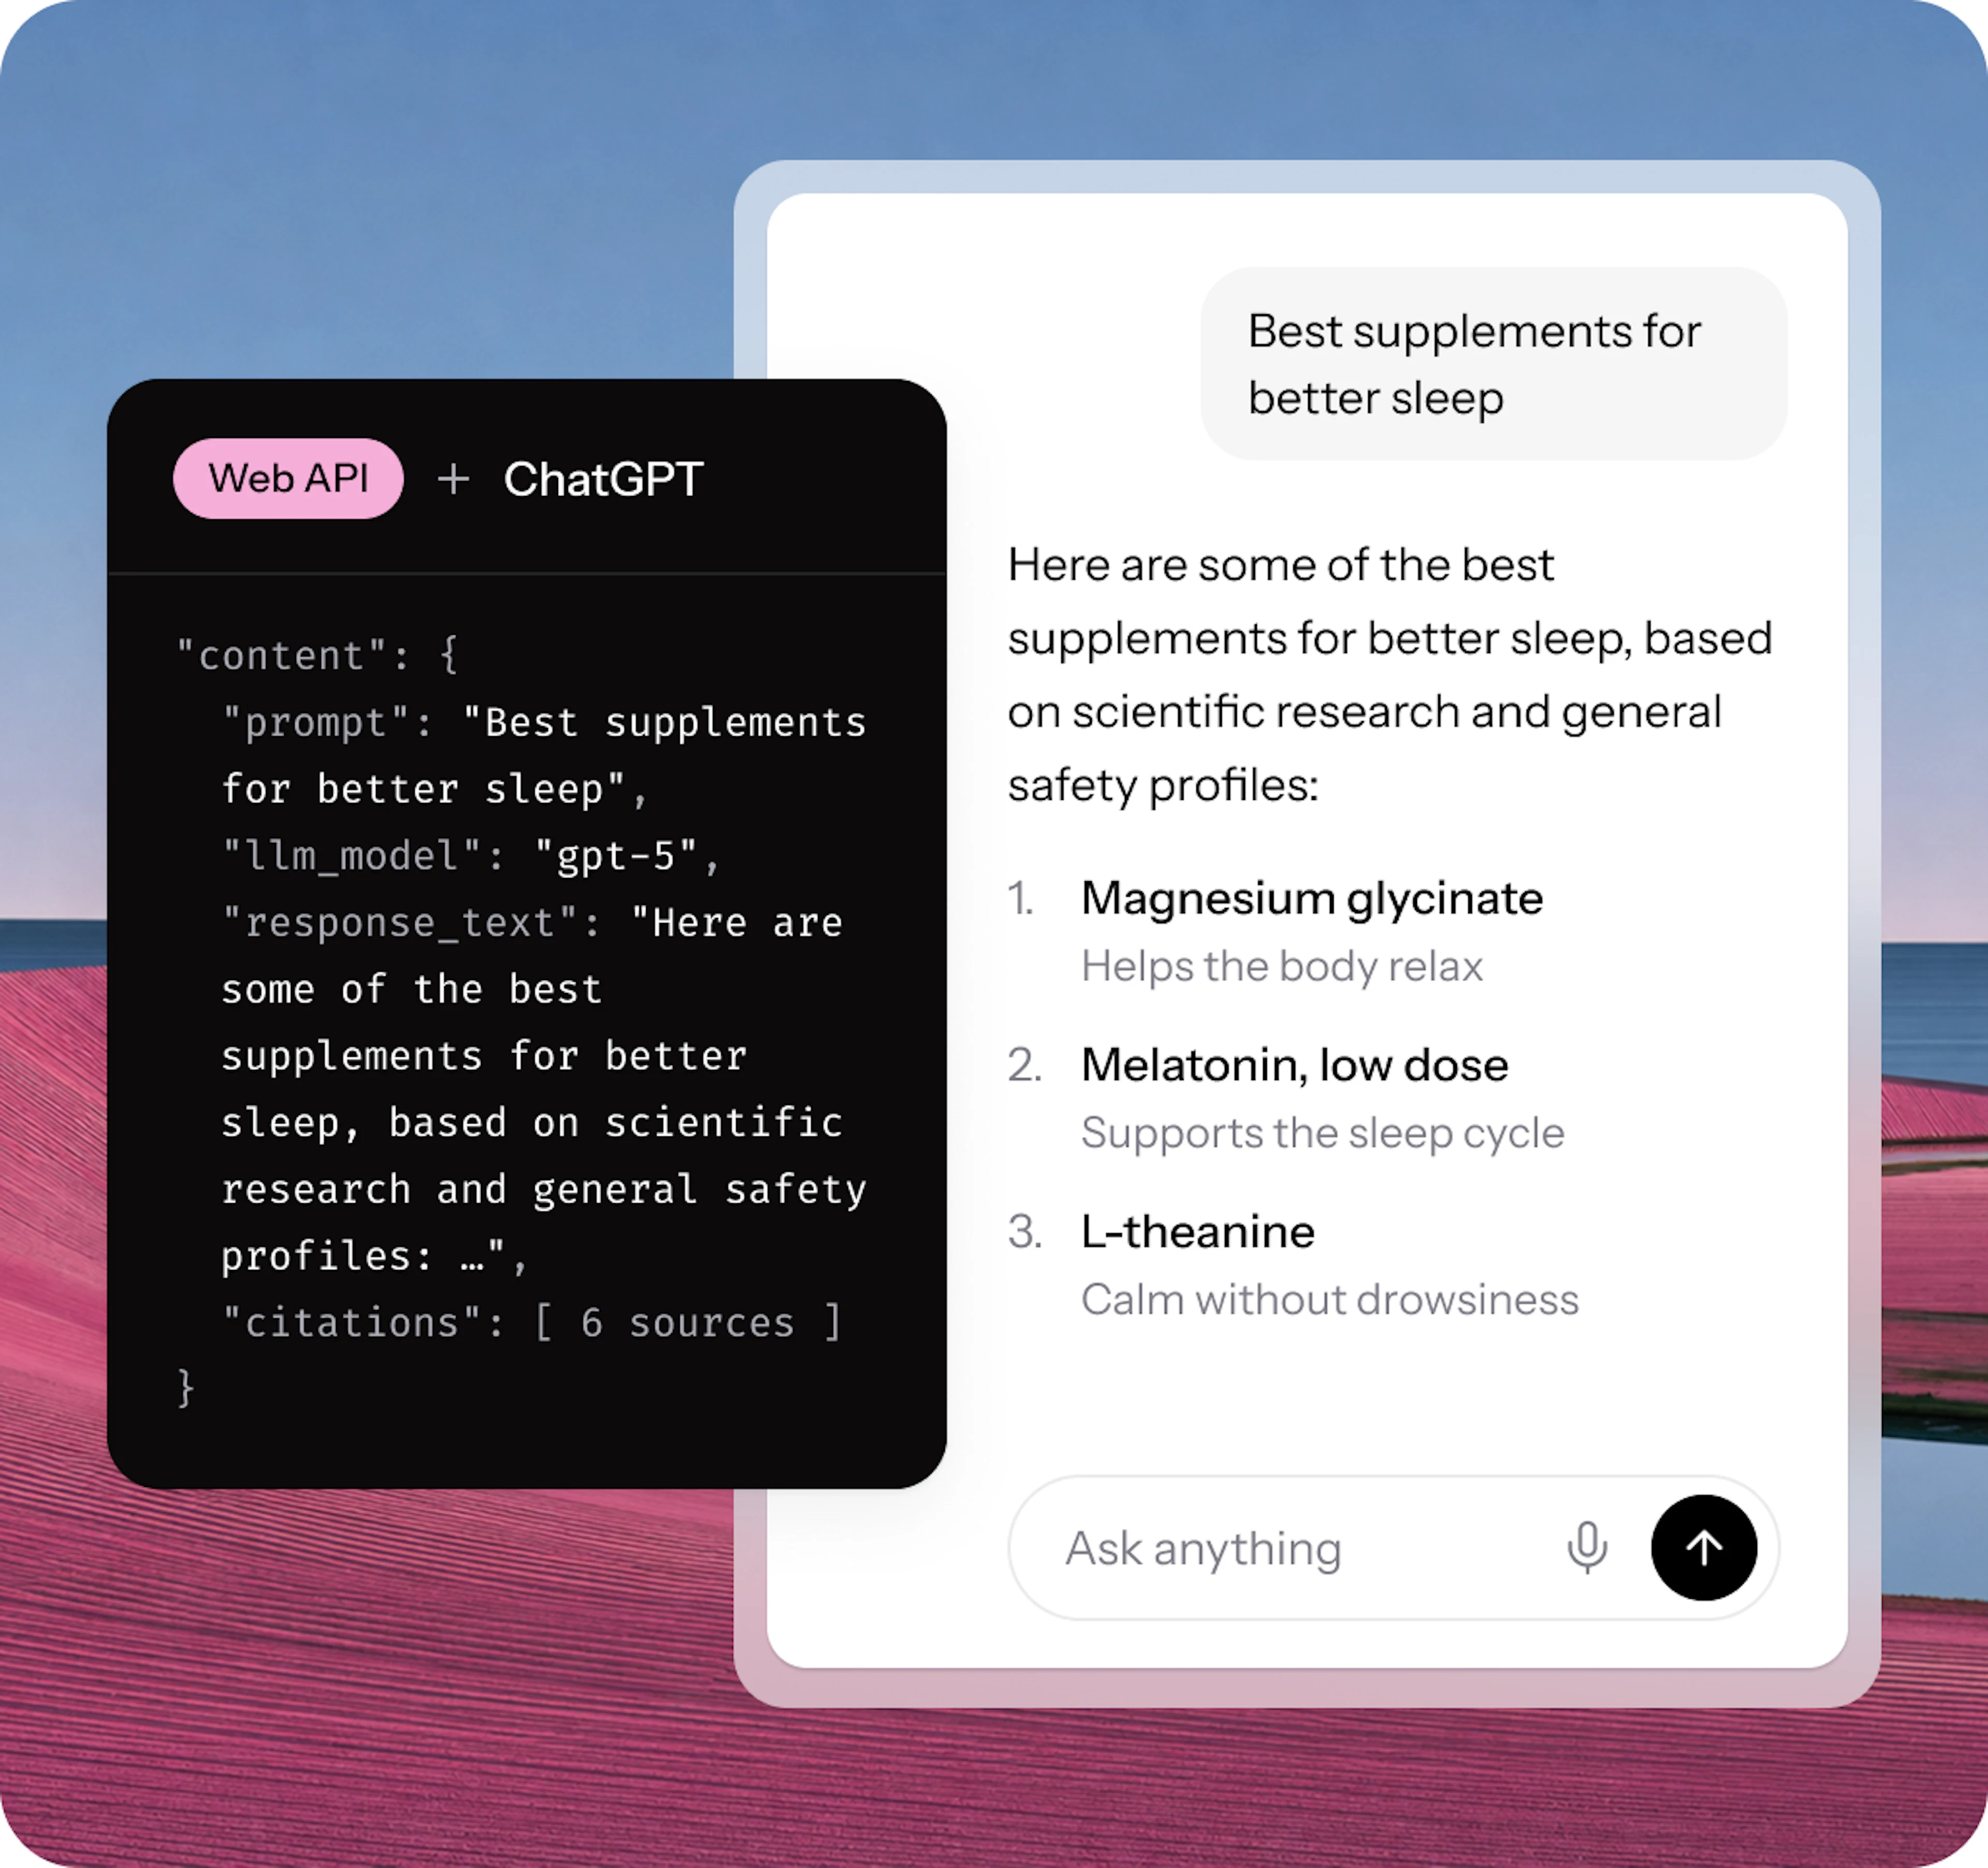
Access accurate, structured ChatGPT-extracted responses, Ads, and Shopping data with country-level geo-targeting.
Built-in country geo-targeting
Live web data with Web Search enabled
Structured, ready-to-use data
Collect ChatGPT organic search results and public Ads & Shopping data at scale, with market-leading success rates.
Rich, geo-targeted ChatGPT insights
Reliable performance at scale
Maintenance-free web scraping
Trusted by 15,000+ clients globally


Access accurate, structured ChatGPT-extracted responses, Ads, and Shopping data with country-level geo-targeting.
Built-in country geo-targeting
Live web data with Web Search enabled
Structured, ready-to-use data
Run high-volume ChatGPT scraping tasks confidently, supported by the industry’s largest proxy pool and consistently high success rates.
175M+ residential IPs across 195 countries
Fully automated, maintenance-free performance
Get optimized, structured outputs
Collect ChatGPT data instantly with no setup, no interruptions, and managed CAPTCHAs – everything is handled for you.
Advanced request handling technology
ML-powered IP pool management
Custom browser instructions for JS-heavy scraping
Scrape ChatGPT conversations hassle-free. Transparent, per-result pricing that scales from a single project to millions of prompts.
Single subscription. All product access.
Welcome credits
FREE
Starter
$30/mo
Basic
$100/mo
Flexible
$500/mo
Enterprise
Custom
/Scrape
From
$0.50/1K res.
Up to 10K results
From
$0.50/1K res.
Up to 60K results
From
$0.45/1K res.
Up to 222K results
From
$0.35/1K res.
Up to 1.43M results
From
$0.25/1K res.
10M+ results
Can't find the plan that suits your business case? Explore more options
Industry-leading success rates
24/7 expert support
Enterprise-grade security & compliance
Real-time spending & usage data
Fast-adapting infrastructure
Scaling with your needs
Get in touch with our customer support team, available around the clock, and resolve your issues anytime.

Built for agents from the ground up, not adapted afterward – with MCP Server, Agent Skills, and token-efficient output.

Handles any request load – run your operations with high success rates and production-grade concurrency.
Reliable extraction from any public site with CAPTCHA & JS rendering handled to succeed even on tough sites.
177M+ ML-powered rotating proxy pool from 195 countries – with no extra work required on your end.
Improved success rates using unique headers, scripts, and fingerprints tailored to each request you send.
Our clients' satisfaction is our highest priority. That’s why we continually invest in enhancing our product performance and provide dedicated support to help customers achieve outstanding results.
Track how your clients' brands appear in ChatGPT for targeted keywords to optimize visibility strategies.
Improve your client's content strategies by aligning with how LLMs and AI agents evaluate and surface information in a particular niche.
Collect diverse, real-world ChatGPT responses to build datasets for training or fine-tuning AI scraping models.
Monitor how competitors are represented in ChatGPT results to refine your positioning strategies.
Step 1: Put your endpoint URL, API key, and data payload into a single request.
Step 2: Send this request to our API. We'll take care of everything from there – you don't need to do anything else.
Step 3: Get the result back either directly from the API or store it in your chosen cloud storage bucket.
import time
import requests
from pprint import pprint


headers = {"Authorization": "Bearer YOUR_API_KEY"}


payload = {
    "query": "what are the best adidas running shoes right now",
    "search": True,
    "output": ["json"],
}


# Submit the job
submit = requests.post(
    "https://webapi.oxylabs.io/v1/async/scrape/chatgpt",
    headers=headers,
    json=payload,
)
job_id = submit.json()["metadata"]["request_id"]


# Poll until the job finishes
while True:
    result = requests.get(
        f"https://webapi.oxylabs.io/v1/async/scrape/{job_id}",
        headers=headers,
    )
    if result.json()["status"] != "pending":
        break
    time.sleep(5)


pprint(result.json())
To extract ChatGPT answers, first you'll need to send a POST request to Oxylabs Web API async endpoint at “/v1/async/scrape/chatgpt”. Include your question as the “query”, and optionally set “search: true” and “output” in your chosen format. You'll get back a job ID immediately, not the result. Then, wait for it to finish: either let us notify you with “callback_url” (recommended), or check the job status yourself. Once the status is done, fetch the raw or parsed response.
You receive structured JSON containing:
— The original prompt
— The LLM model identifier (e.g. gpt‑4o)
— Full ChatGPT output (e.g. markdown blocks, raw text)
— Parsed fields requested via output: ["json"] (e.g., response_text and markdown_text)
These include full content, such as citations, links, timestamps, as well as metadata, like search behavior and geographic origin of the request.
Yes. Every ChatGPT scraped response data is validated and parsing checks before it reaches you, so malformed or incomplete results are caught rather than shipped. That's why the output comes in a format that is ready to load straight into your database or AI scrape pipeline.
You're only charged for successful results. Failed requests don't consume API credits. Results with JavaScript rendering are billed at a slightly higher per-1K rate, and media downloads are billed per GB, as shown in the pricing table above.
Responses can be retrieved directly via the API (push replies) or configured to send results to a callback_url endpoint. Additionally, output can be delivered into cloud storage services like AWS S3, Google Cloud Storage, Alibaba Cloud OSS, Tencent Cloud Object Storage (TOS), and other S3-compatible destinations using the storage parameter.
No. CAPTCHA handling, retries, proxy rotation, and fingerprint mechanisms are fully automated. You send a prompt to the ChatGPT scraper, we manage the reliable access and return clean, structured, scraped data.
Yes. Backed by 175M+ residential IPs across 195 countries and rate limits up to 100 requests/second, the API is built for high-volume, geo-targeted collection without added maintenance. Because the Web API handles all headless browser rendering, proxy rotation, and infrastructure on our side, you don't need to manage or scale automation tools like Selenium or Playwright, making it highly efficient for large-scale projects.
You can request multiple formats in a single API call using the output array parameter. Available formats include JSON (for structured fields like the model's answer and citations), Markdown (for clean, token-efficient text), and HTML. Cloud delivery options package these results in JSON before sending them to your designated storage bucket.
Oxylabs recommends reviewing the target’s Terms of Service and getting legal advice before scraping. In general, web scraping publicly‑available content may be legal, but legality depends on factors like data type, jurisdiction, usage, and contract terms (TOS or robots.txt). Other sources note that while public scraping is often permitted, unauthorized access, copyright infringement, privacy laws (for example, GDPR), or breach of contract can create legal risks.
ChatGPT official API (OpenAI’s endpoint) provides conversational interface and structured responses via its own API, under OpenAI’s terms and rate limits.
Oxylabs Web API simulates real user interactions with ChatGPT UI, allowing geo‑targeting (e.g. simulate prompts sent from particular countries or cities) and returns both the unmodified interface response and metadata including context and layout structure. It also supports web search augmentation (search: true) which triggers ChatGPT’s own search feature in UI mode – something not available in OpenAI’s endpoint API.