Your Agent Lives in the Now – Feed It the Now
Search the web, extract structured data, and deliver clean real-time context to your models with one API at scale.
Trusted by 15,000+ clients globally:


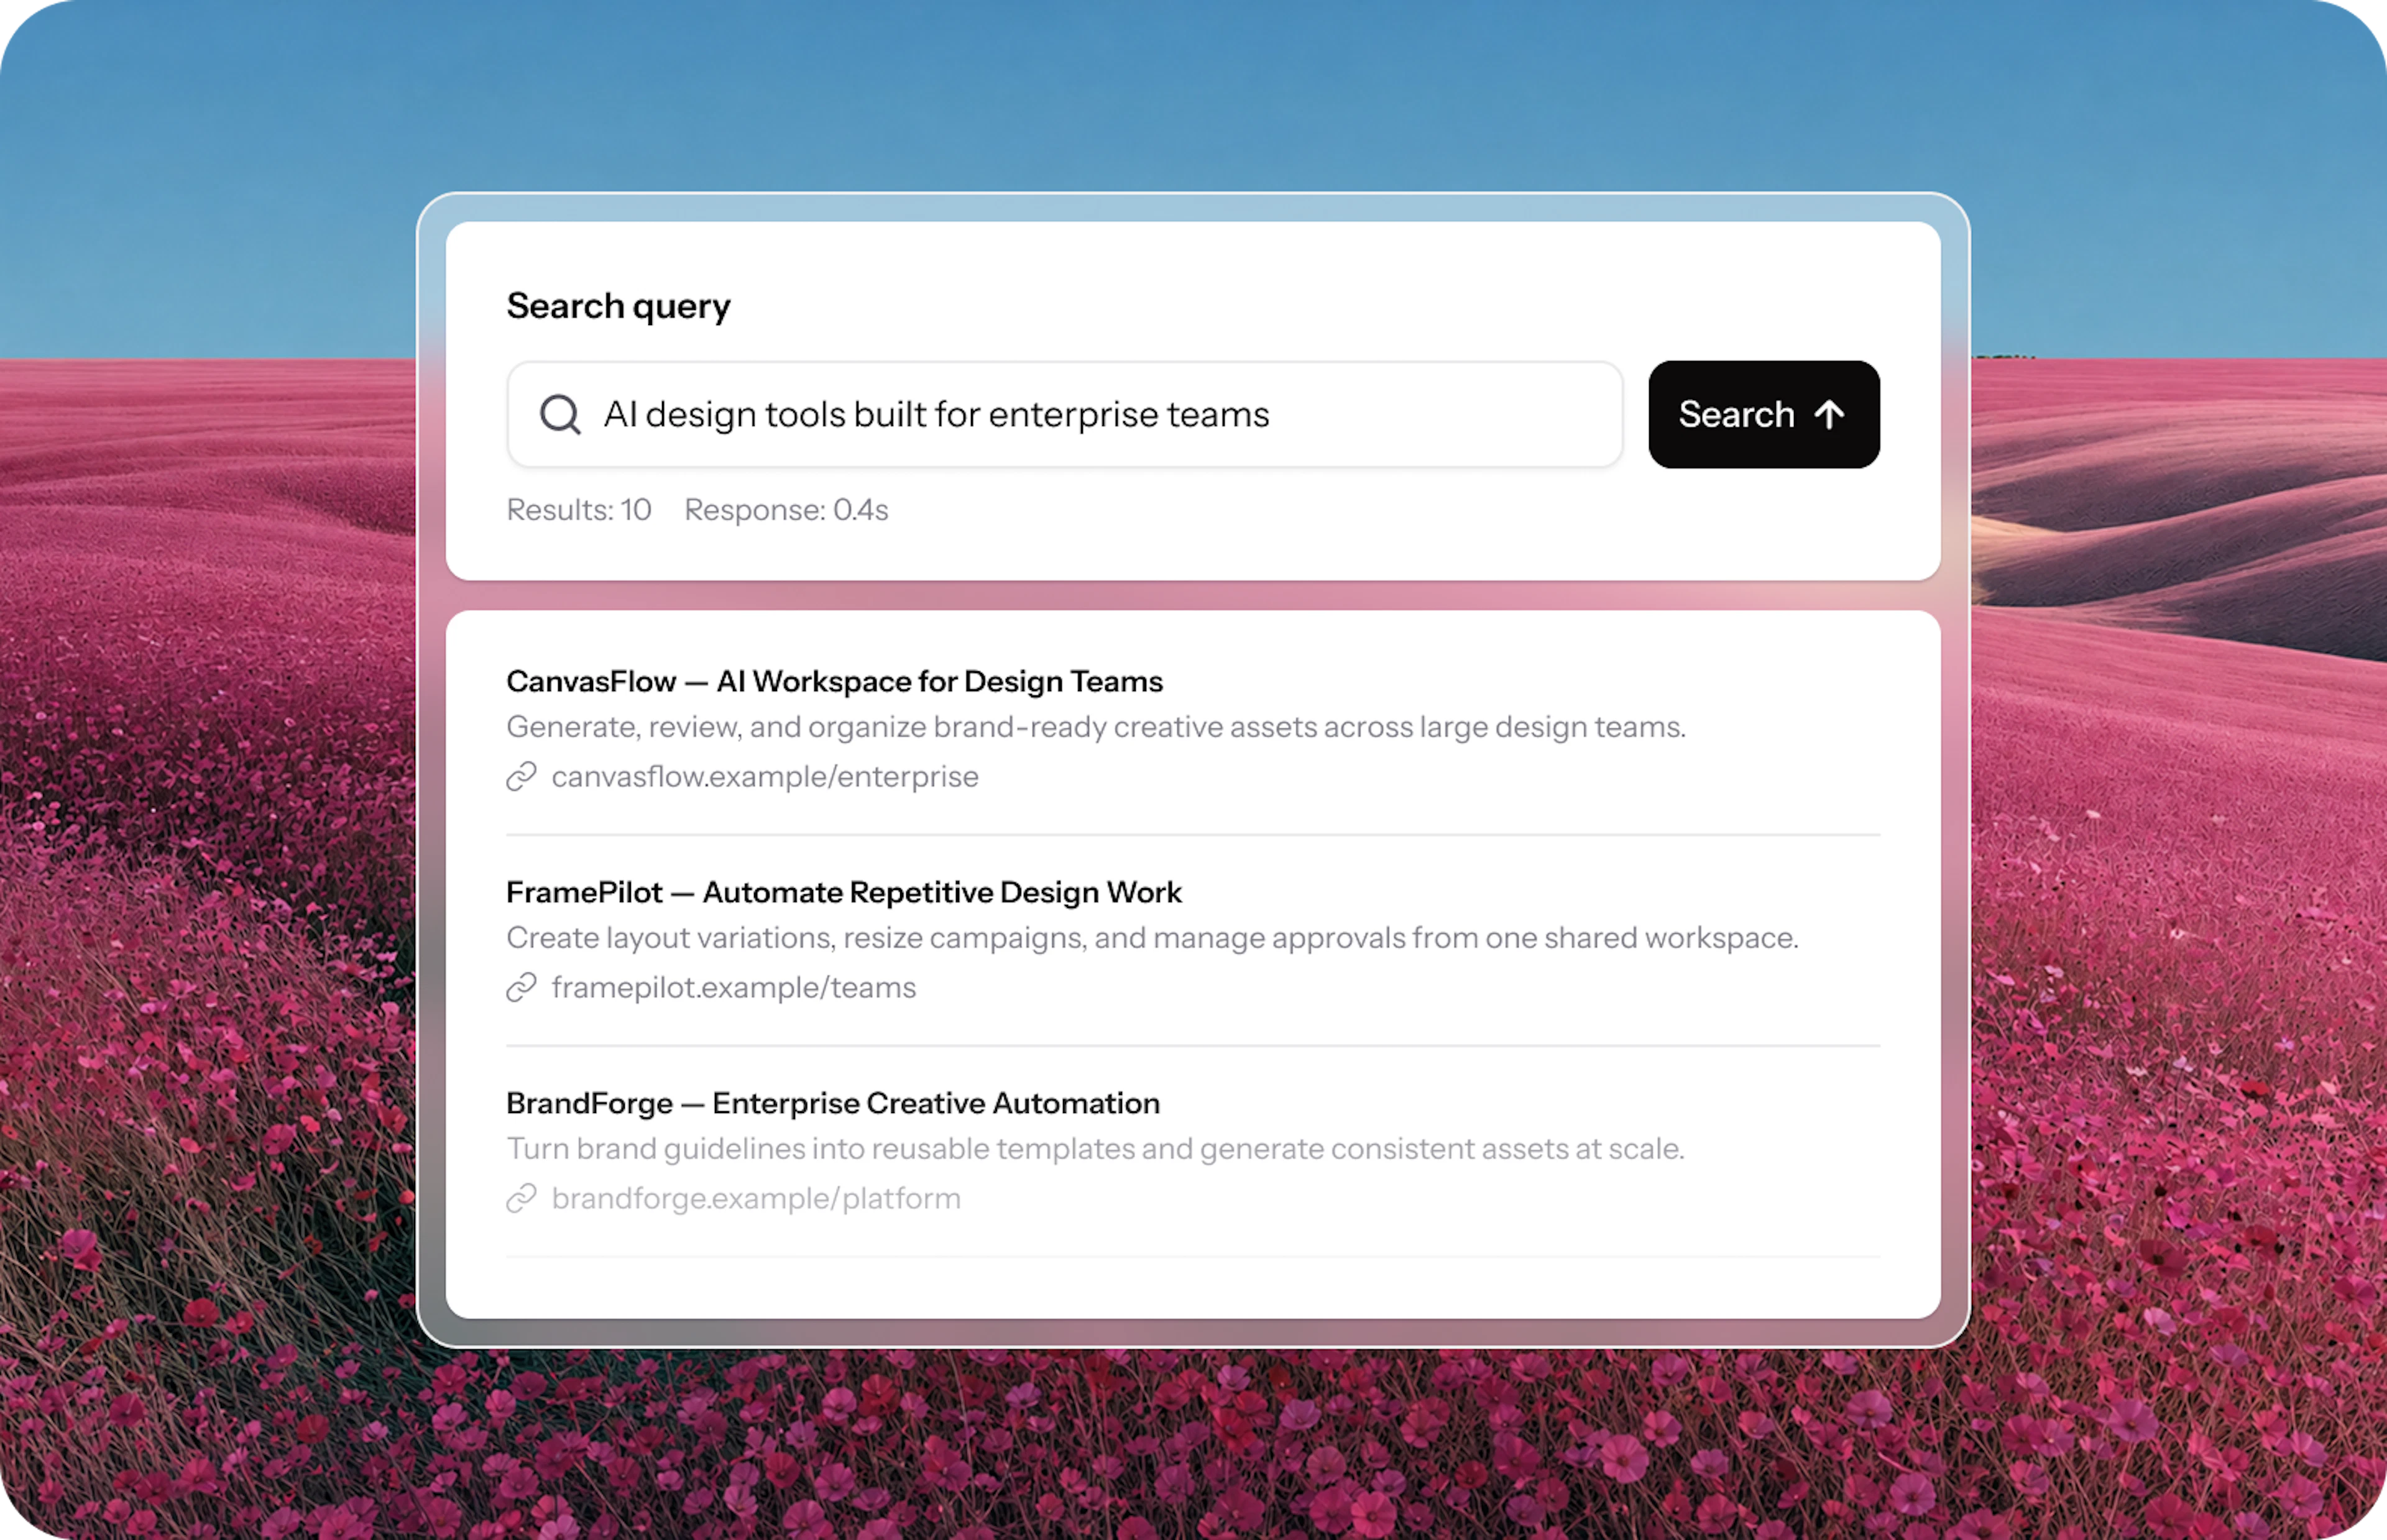
Web discovery
Find the most relevant search results across the live web from a single query – no need to know the target website in advance.
Fresh, real-time results
Discover current content pulled from the live web on every call, so your agents work with what's happening now.
Relevant, ranked sources
Get the most relevant results surfaced first, ranked for the query and localized to your target country.
Web data extraction
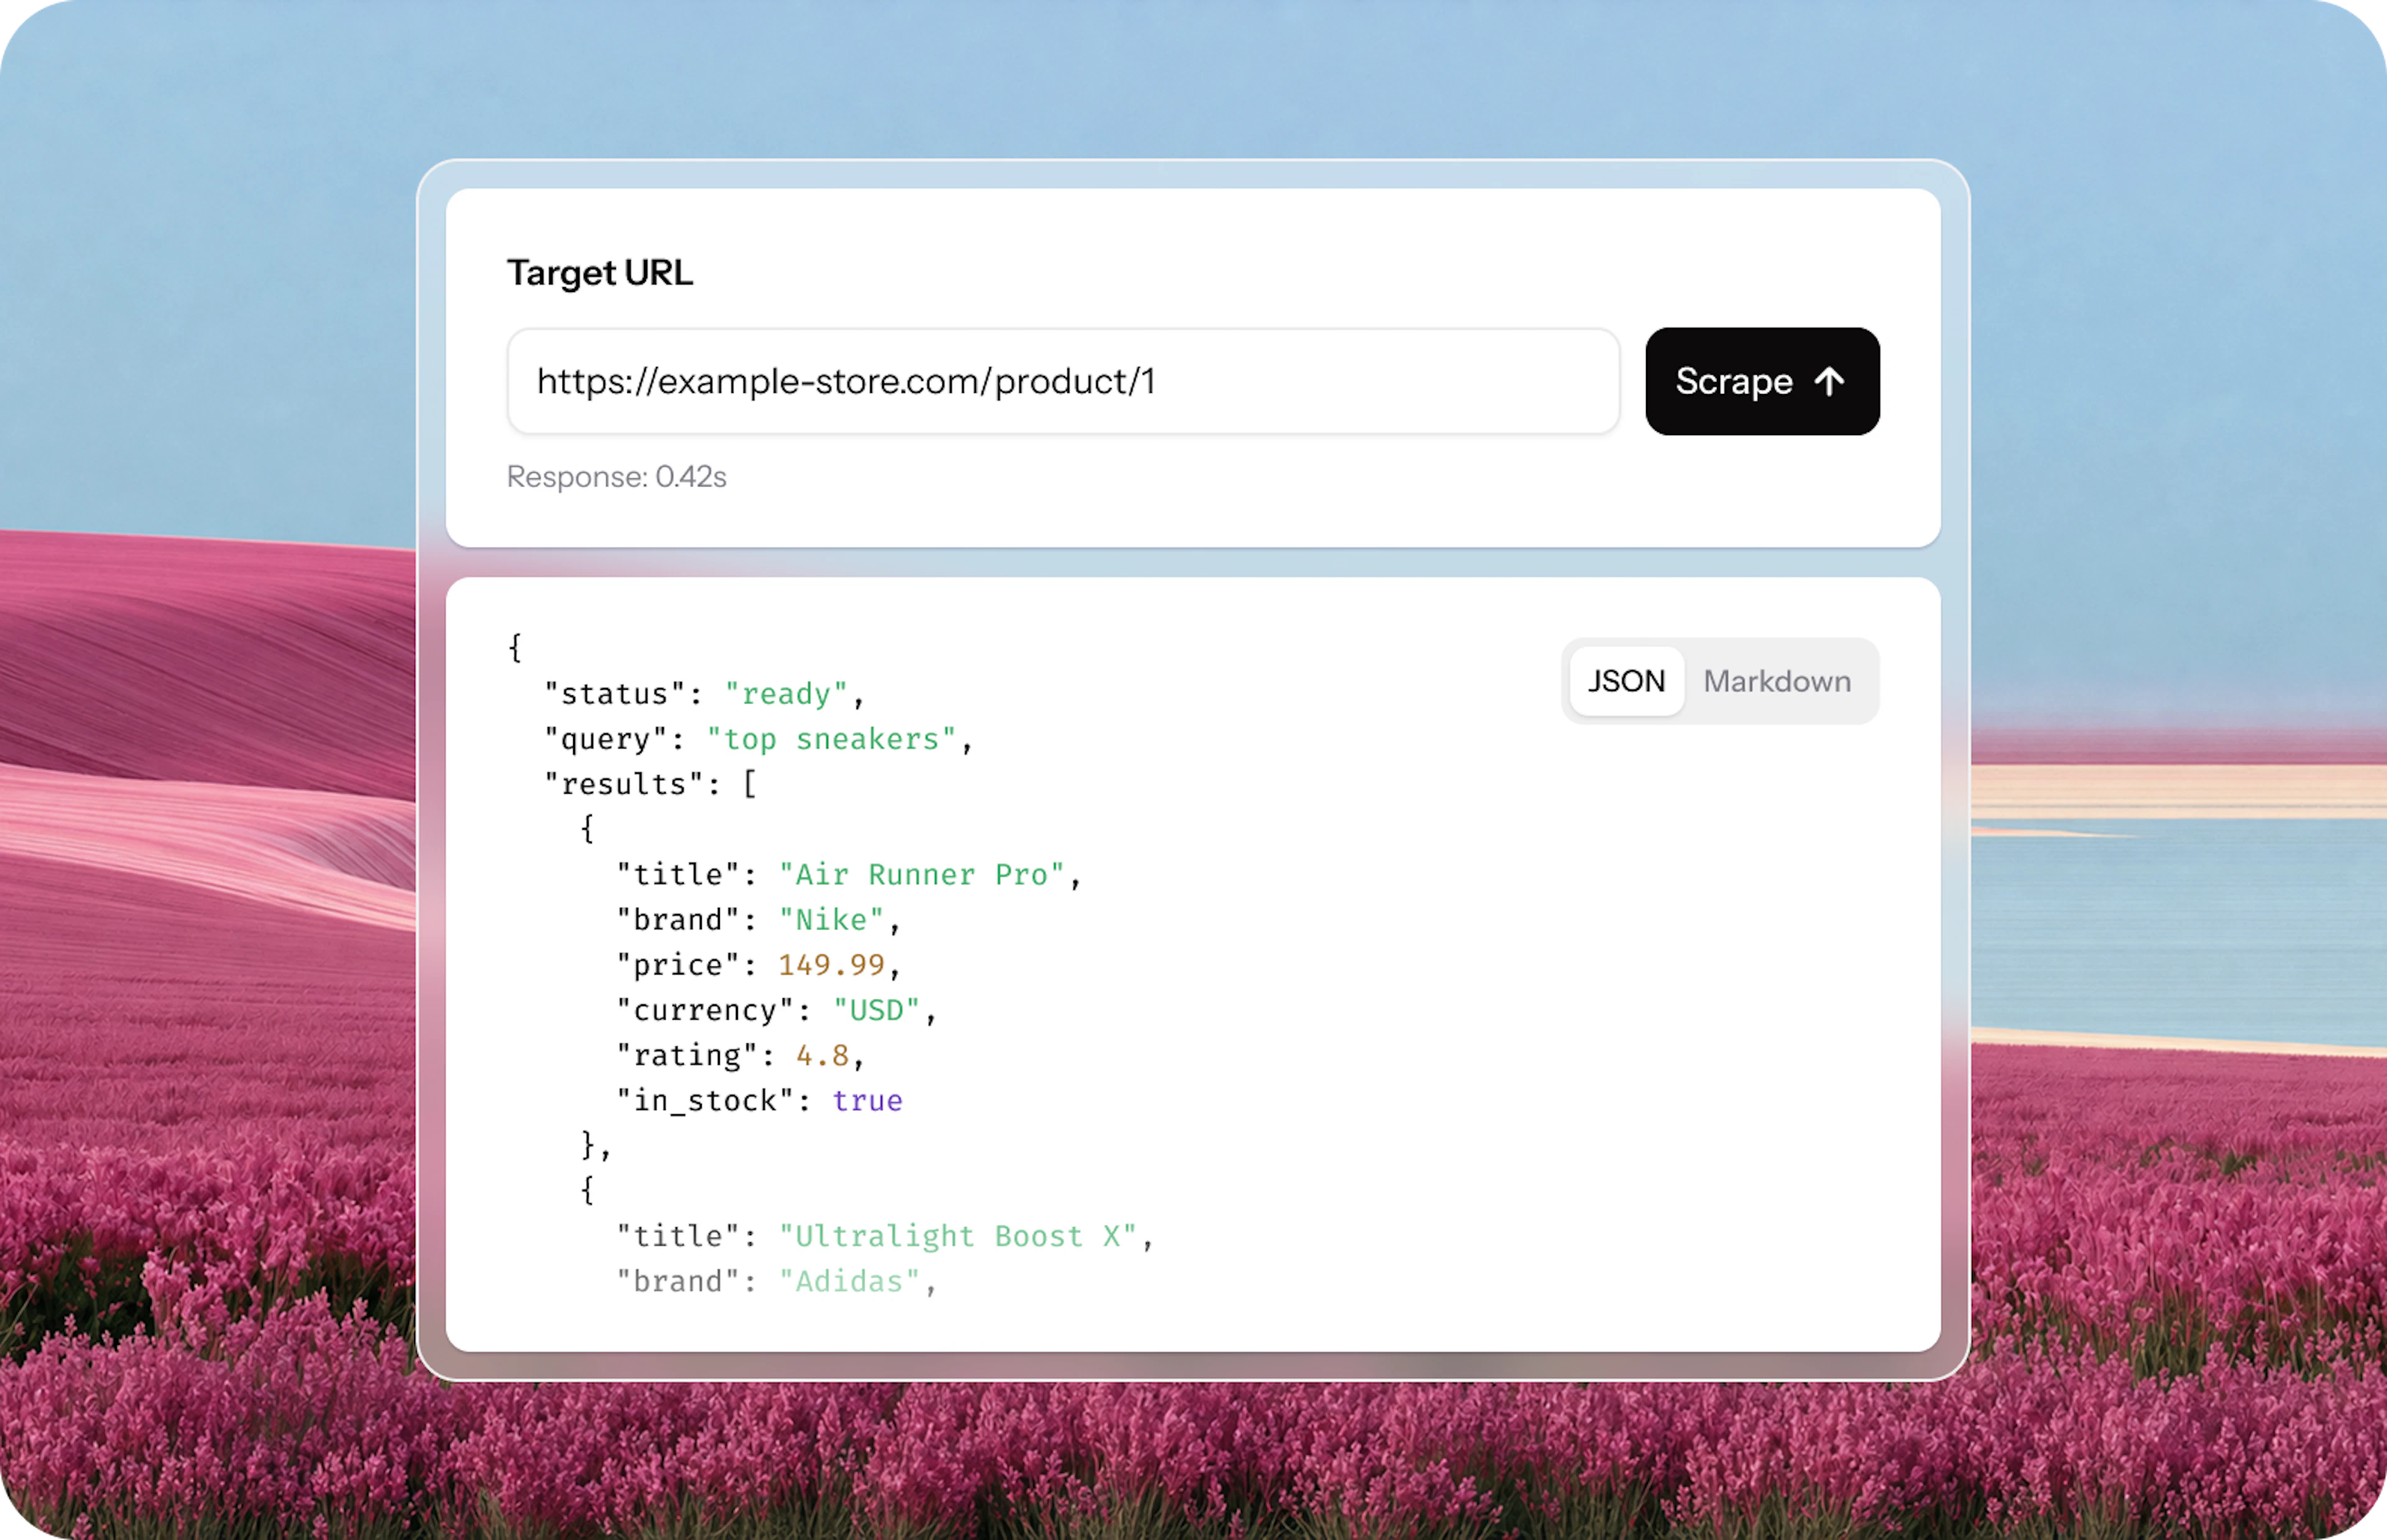
Reliably collect clean, structured data from across the web – no infrastructure, maintenance, or downtime to worry about.
Fast-adapting infrastructure
Maintain stable data access despite web changes or dynamic content through a constantly updated and maintained scraper.
Accurate & structured data
Retrieve analysis-ready data with a Custom Parser using XPath or CSS selectors, or AI Parsing that works on any link.


Native for agents
MCP Server and Agent Skills for instant agent access.

Web API pricing
Single subscription. All product access.
- Search
- Scrape
- Residential Proxies
- Mobile Proxies
- ISP Proxies
- Dedicated Datacenter Proxies
- Datacenter Proxies
- Web Unblocker
- Agent Browser
Welcome credits
FREE
Starter
$30/mo
Basic
$100/mo
Flexible
$500/mo
Enterprise
Custom
/Search
$1/1K searches
Up to 5.6K searches
$1/1K searches
Up to 30K searches
$1/1K searches
Up to 100K searches
$1/1K searches
Up to 500K searches
$1/1K searches
2.5M+ searches
/Scrape
From
$0.50/1K res.
Up to 10K results
From
$0.50/1K res.
Up to 60K results
From
$0.45/1K res.
Up to 222K results
From
$0.35/1K res.
Up to 1.43M results
From
$0.25/1K res.
10M+ results
Can't find the plan that suits your business case? Explore more options
Why our products are the best choice
Industry-leading success rates
24/7 expert support
Enterprise-grade security & compliance
Real-time spending & usage data
Fast-adapting infrastructure
Scaling with your needs
Live web context for AI agents
One API for search & retrieval
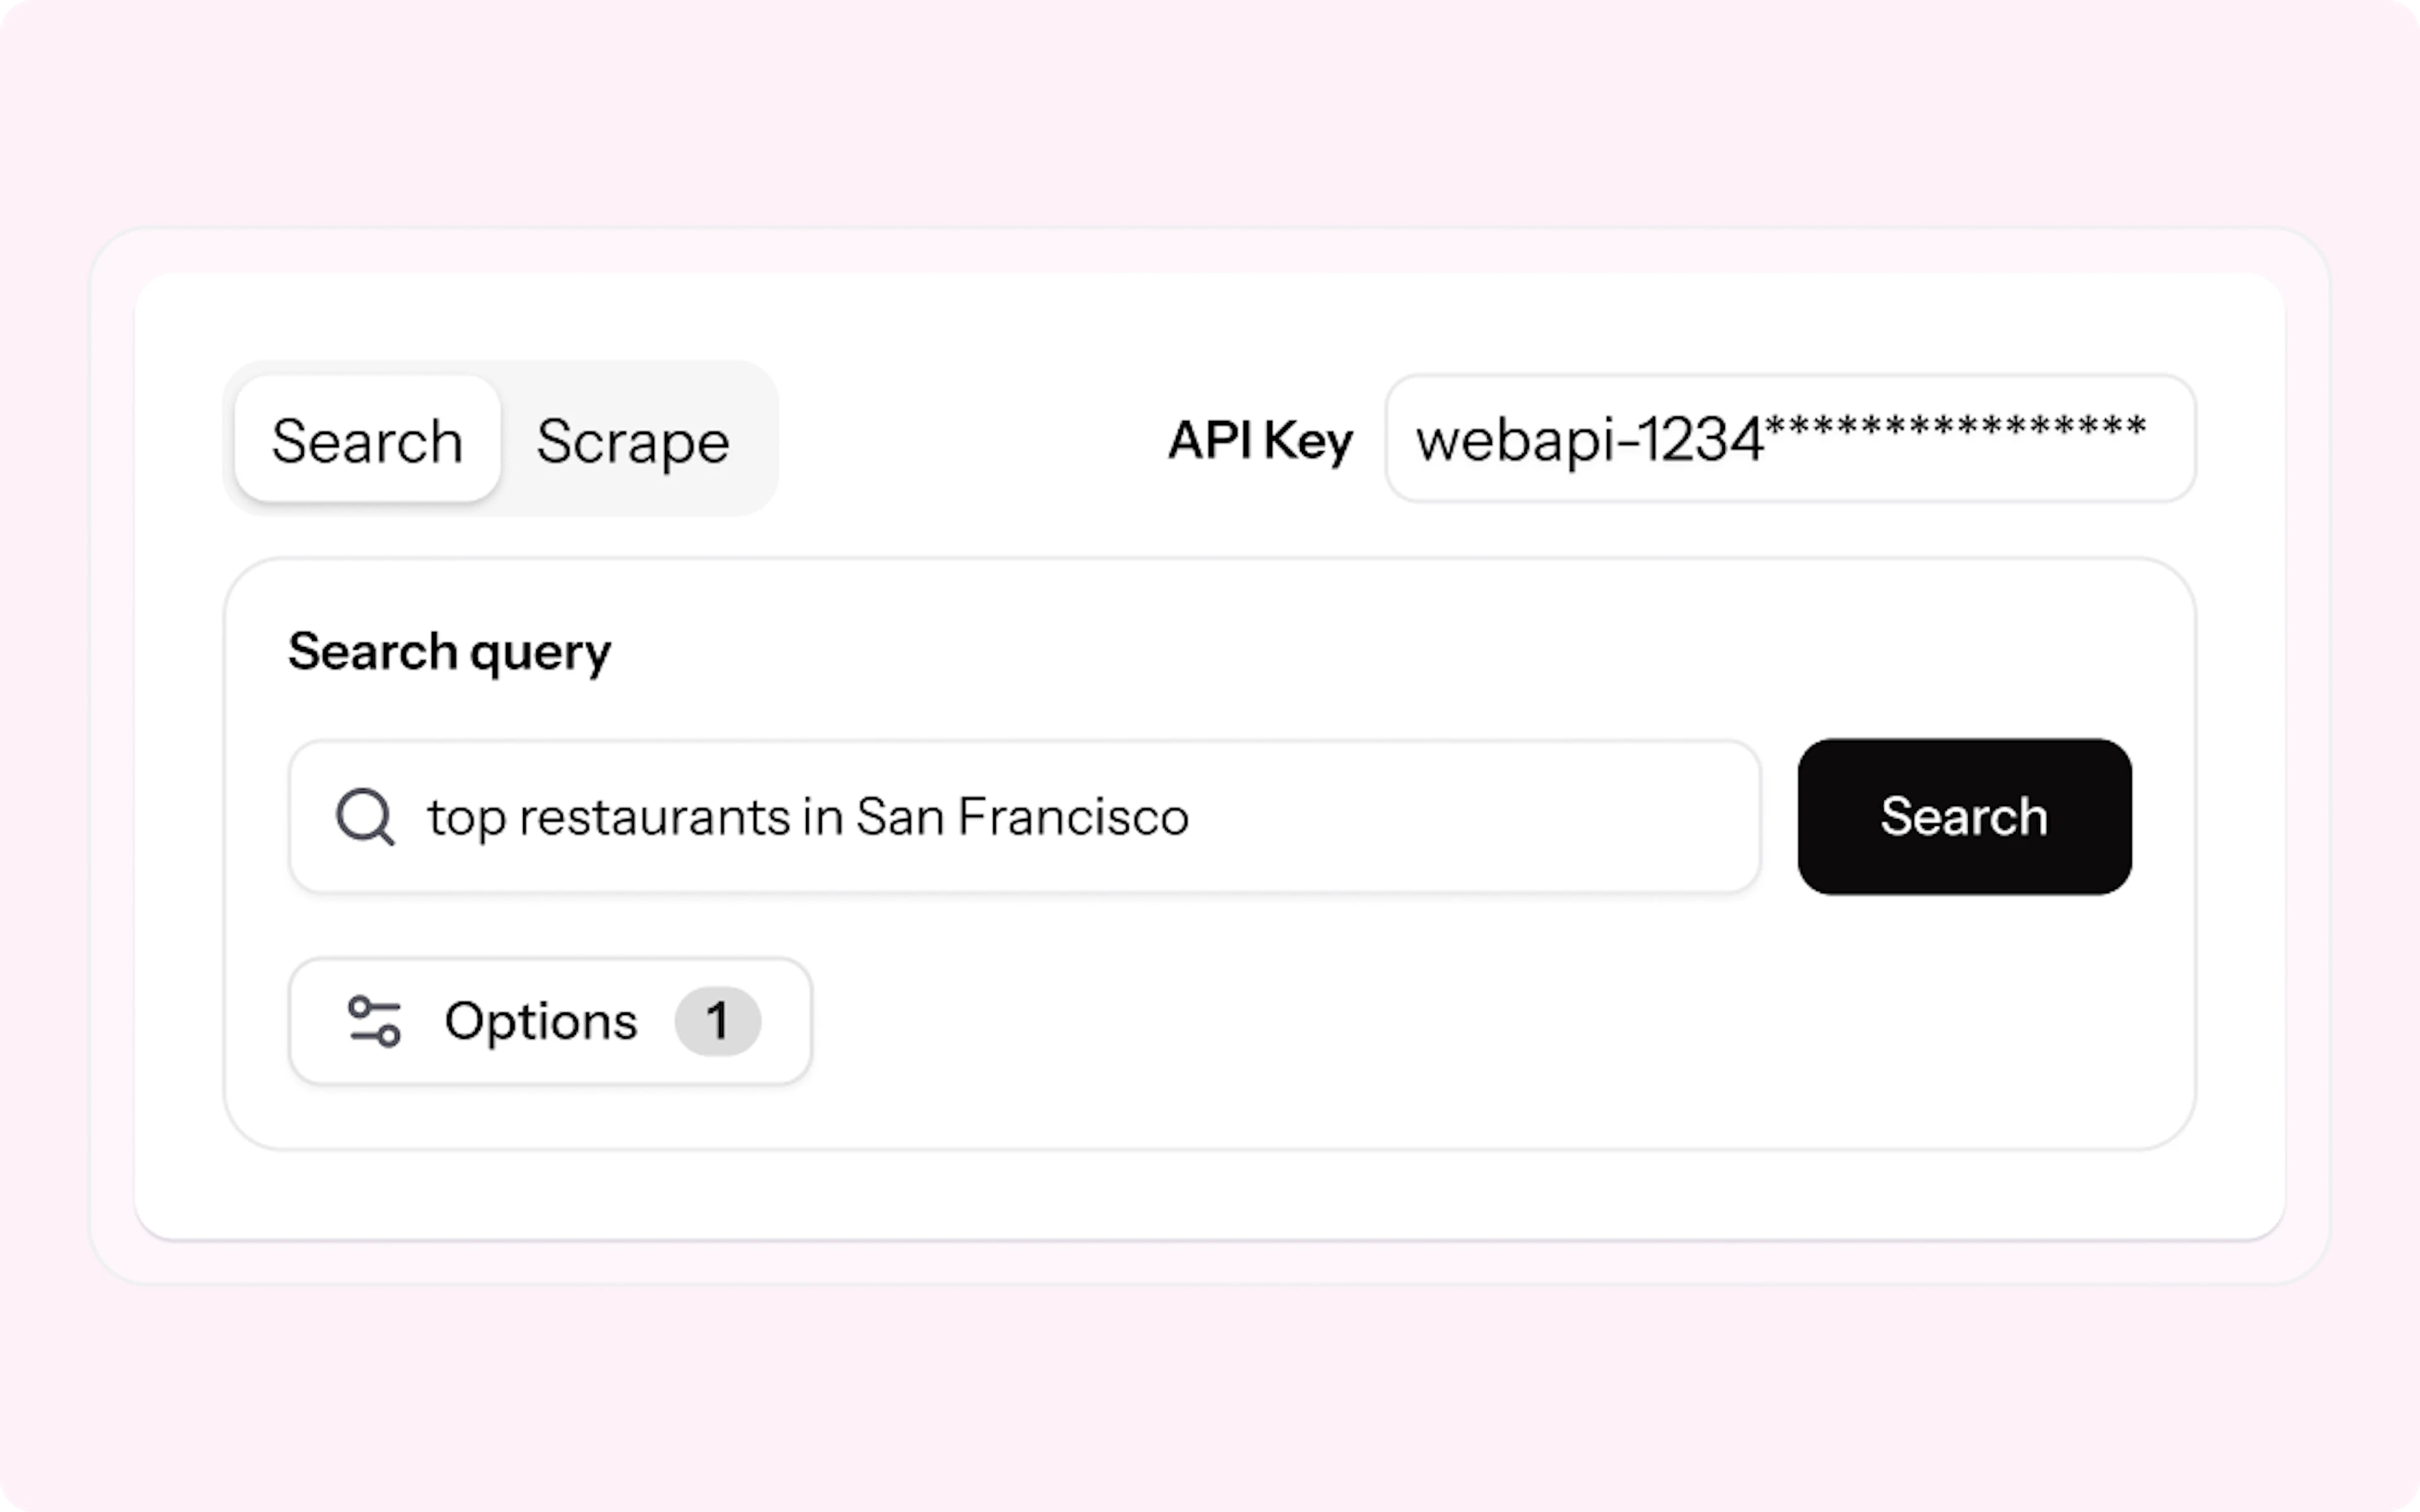
One key, one dashboard. Discover sources and retrieve data through a single API without stitching separate providers together.
Fresh data on every request
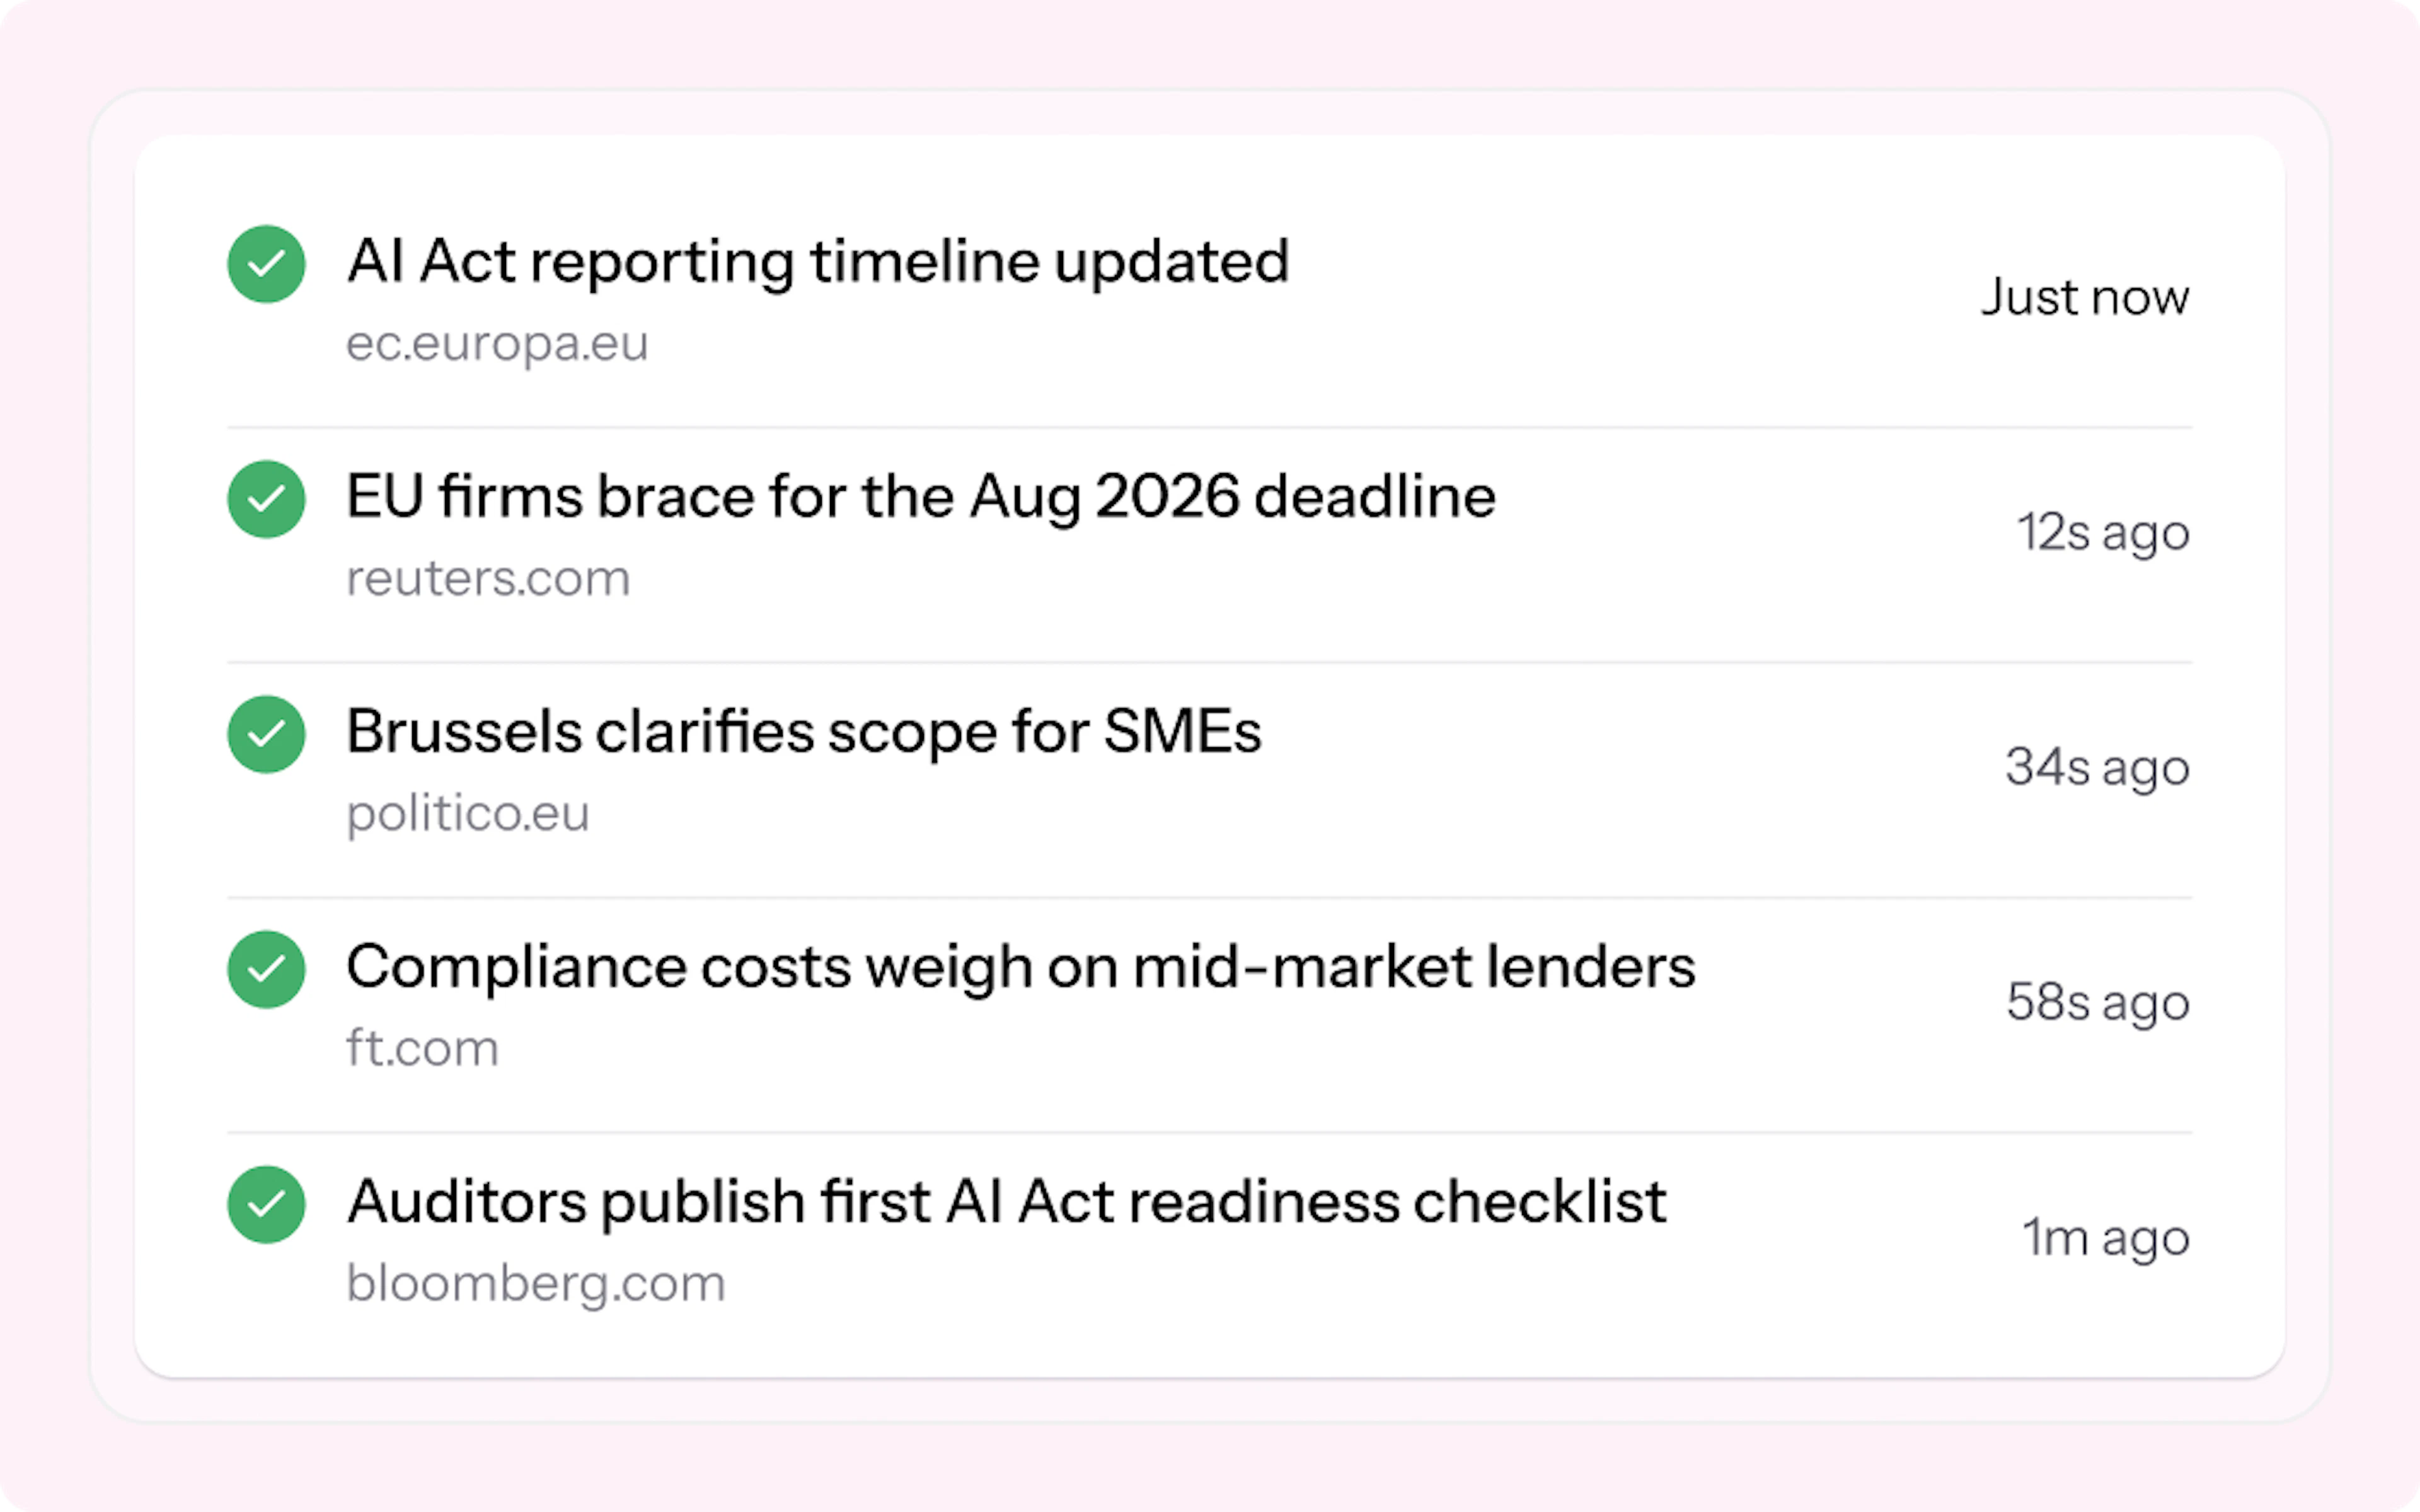
Real-time results on every call, served from live web rather than a cached index. Let your agents work with what’s true now.
Reliable access to the whole web
177M+ IPs across 195 locations and 99.9% uptime – reliable retrieval on the most demanding targets, from JS-heavy pages to complex sites.
Agent-native by design
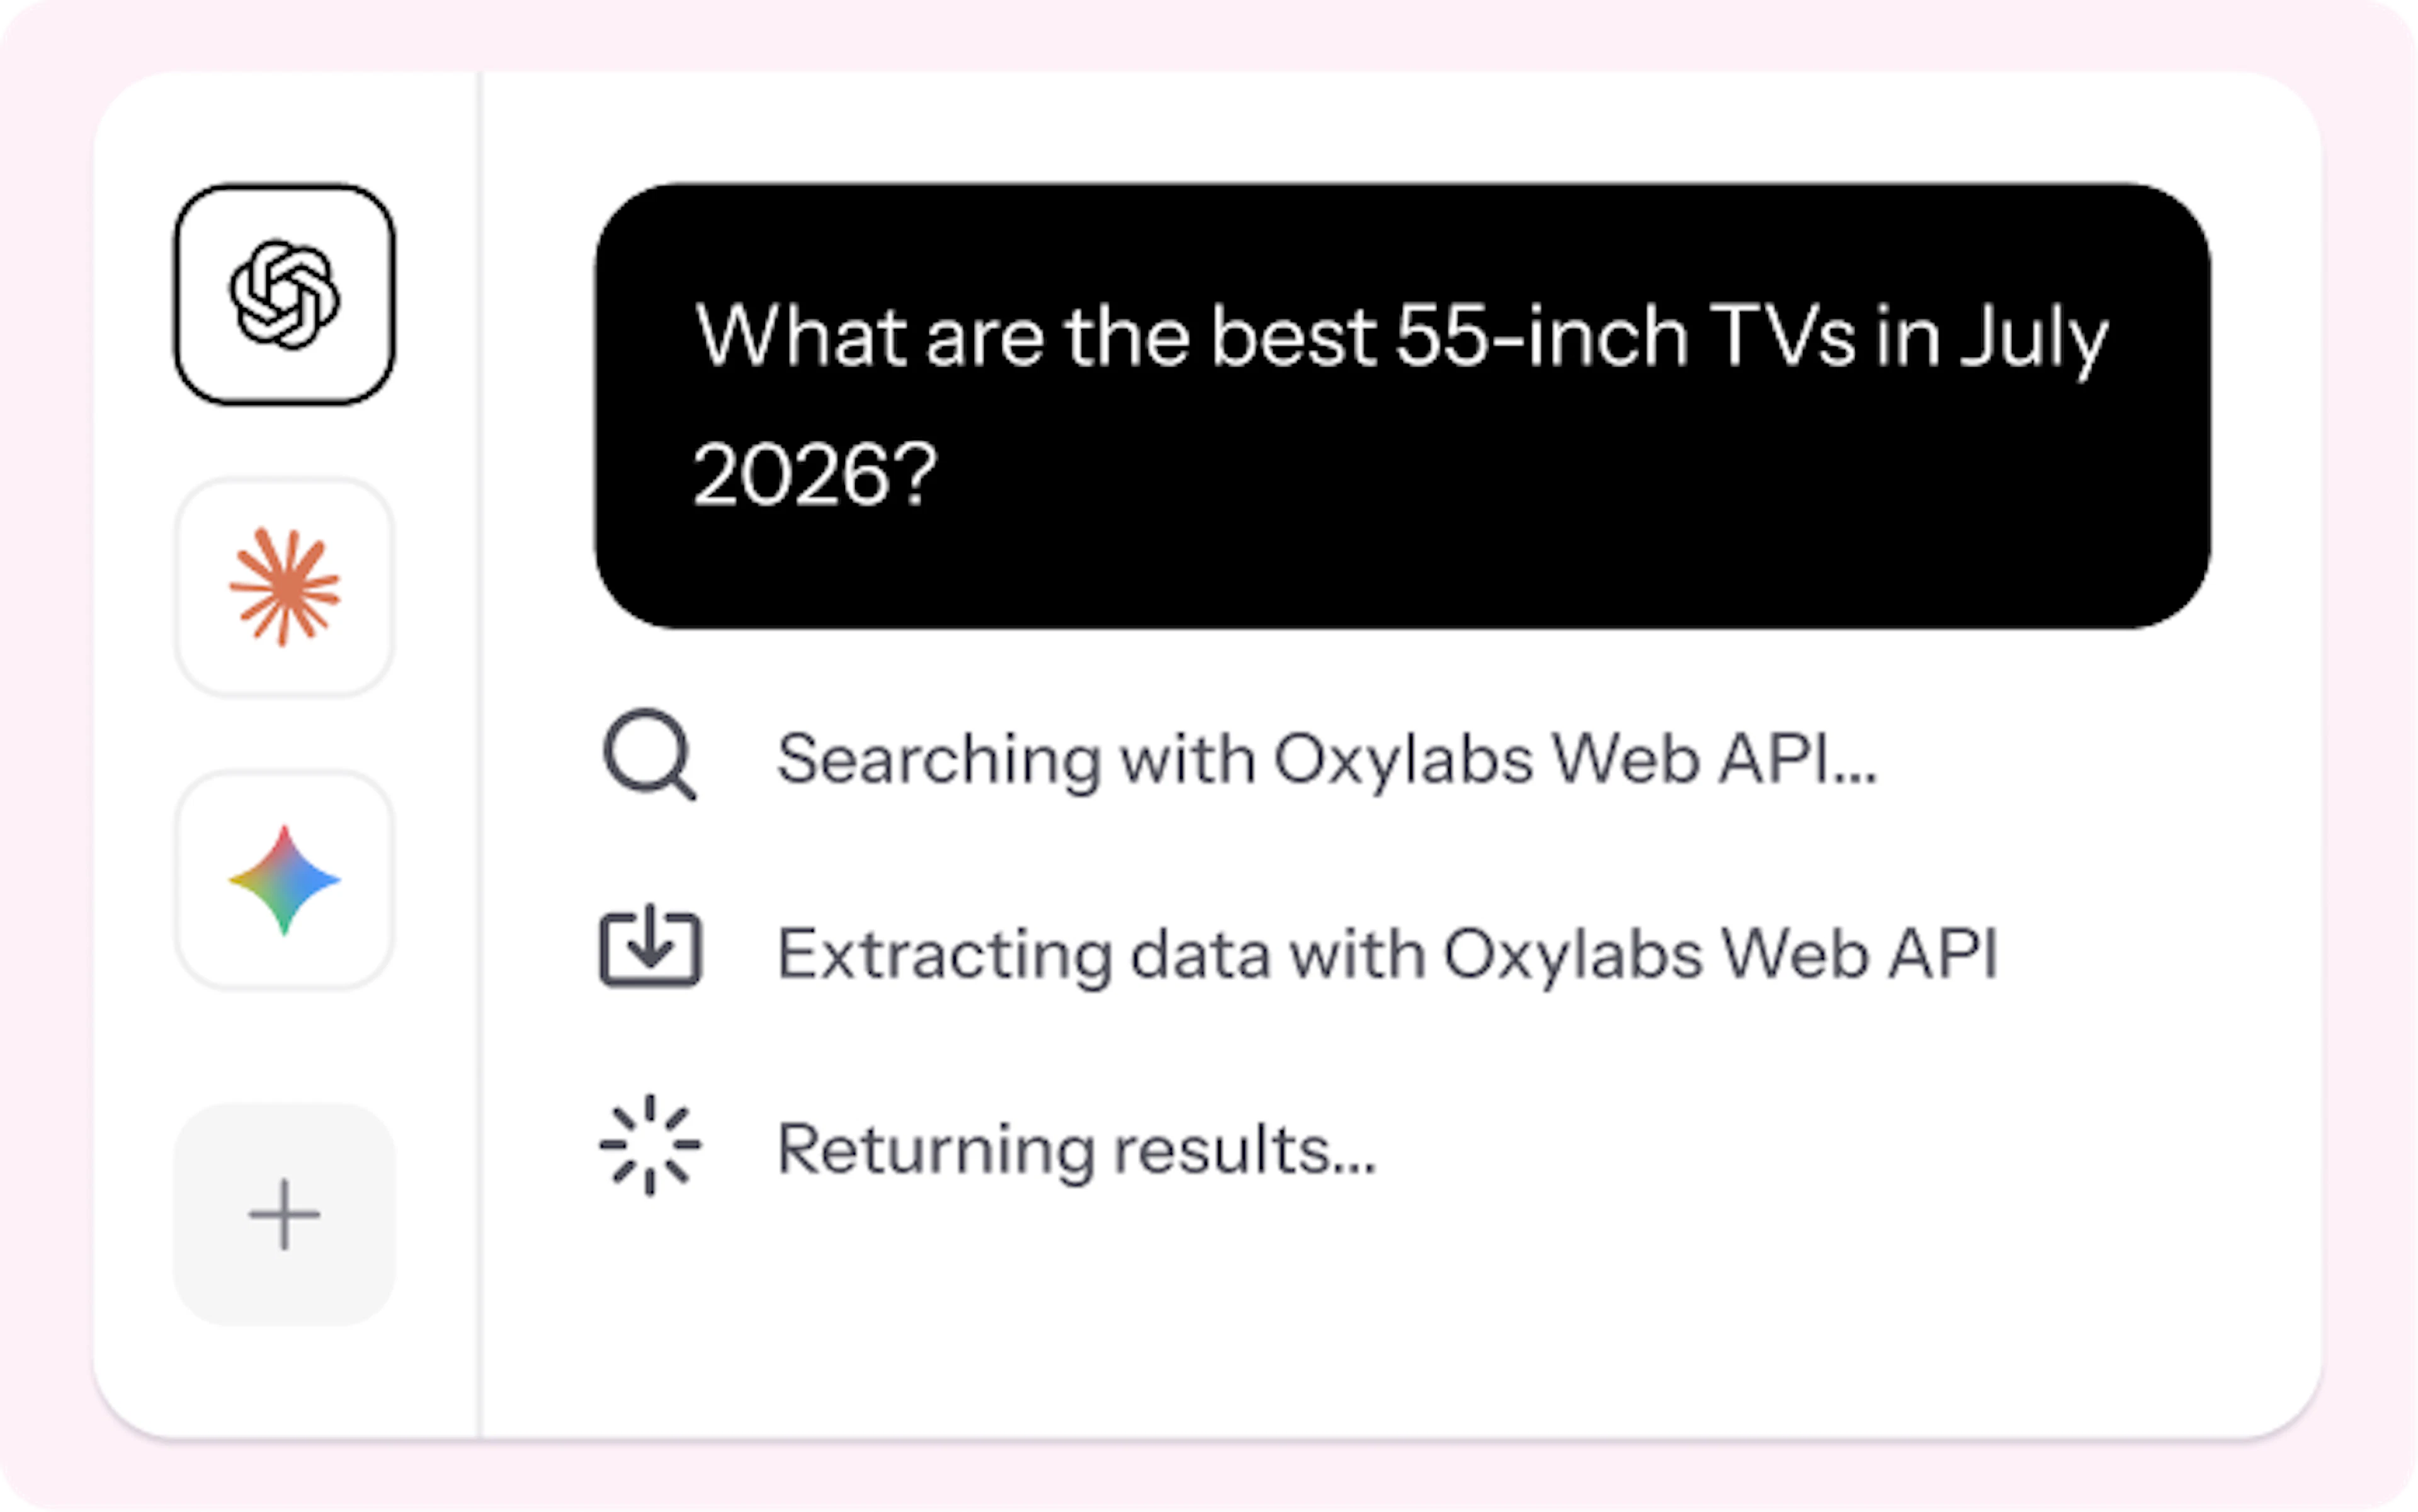
Built for agents from the ground up, not adapted for agents afterwards – MCP Server, Agent Skills, and token-efficient JSON or Markdown output.
Enterprise-grade scraping infrastructure
ISO 27001 certified and backed by 11+ years of expertise – the compliance and reliability large-scale projects require.
One key, one dashboard. Discover sources and retrieve data through a single API without stitching separate providers together.
One API for every web data workflow
The Search endpoint discovers what to look at, while Scrape endpoint retrieves it in full. Together they cover the way teams actually work with the live web – from grounding agents to tracking competitors.
Agent grounding & RAG
Ground AI applications in real-time web data – /search finds relevant sources; /scrape retrieves clean content for context or indexing.
Enterprise research automation
Evidence-backed research at production scale – /search gathers evidence across sources; /scrape pulls full content for analysis and reports.
Competitive & market intelligence
Spot competitor and market shifts faster – /search discovers new competitors and mentions; /scrape monitors known pages for changes.
E-commerce & product intelligence
Track products, pricing, and availability across marketplaces – /search finds listings; /scrape extracts prices, stock, and reviews.
Sales & GTM enrichment
Build and refresh company and prospect records – /search finds accounts, people, and signals; /scrape enriches with firmographics and profiles.
Monitoring & risk intelligence
Turn important changes into structured alerts – /search surfaces filings, recalls, and updates; /scrape retrieves full documents and monitors known pages.
The whole web, one API
call away
Starts from
$0.25/1K results
Why teams choose Oxylabs
Companies rely on our infrastructure wherever fresh, structured web data matters.
Runs millions of requests daily, reliably
"Today we rely on Oxylabs for stable scraping, IPs that work, and fast, responsive support. [...] It's not just about changing an IP – it's about the right support, constant innovation, and being treated as a real partner."
Hocine Amrane
Agile Rollout Senior Director
Retrieves the freshest retail insights
“Oxylabs proxy offerings are a critical part of Wiser’s workflows. [...] we execute crucial data operations and provide our clients with the freshest retail insights.”
Devon Kelly Walczak
SVP Operations
Provides clients accurate, current data
“We saw marked improvements in data quality, operational efficiency, and our ability to provide customers with accurate, location-specific advertising information.”
Javier Vázquez Rodríguez
Managing Director
Enjoys 100% fresh data delivery rate
“It’s given us peace of mind that we have a reliable solution that we are certain can scale into the future, while saving us significant time and cost.”
Andrew Mabbott
Head of Development
A web data API is a simple API that lets you collect live information from web pages and receive it in structured formats, ready for direct use. Instead of building and maintaining a web scraper yourself, you send API requests and get clean data back – no proxy management or parsing to handle. It's used for data collection at scale: powering data pipelines, gathering business data and market signals, and feeding AI workflows with fresh web content.
You send a request to a single REST API with your API key, choosing the endpoint that fits your task. The Web API offers two: use /search when you don't know where to look – it discovers and ranks relevant source URLs in real time, returning each result with a title, snippet, and position metadata. Each endpoint works independently, so you call whichever you need, when you need it. Use /scrape when you already have the URL – it launches a web scraper via API that handles JavaScript rendering, proxy rotation, and access to complex websites, then returns high quality web data in structured formats like JSON or Markdown. You can extract data from modern websites at scale without managing infrastructure, and choose the LLM-ready output formats that fit your pipeline, including structured JSON.
AI agents and LLM systems are only as good as the data they work with. Training data goes stale, so agents need real-time data from the live web to reason accurately. Extracting data from raw HTML and turning websites into clean, structured data (such as markdown or parsed JSON) gives AI systems reliable, current context to act on. Delivered in LLM-ready data formats, this lets agents ground their answers in real business information rather than outdated knowledge.
Look for reliability, coverage, and scale. The best provider should deliver high quality web data consistently – with a high ratio of successful requests to failed requests, even on complex websites. Check whether it supports large scale data extraction, handles proxy management for you, and returns clean data in the structured formats you need. A flexible scale plan, strong infrastructure, and clear documentation matter too, so the service grows with you from testing to production.
A traditional web scraper and other tools often return raw HTML that you still have to clean, parse, and maintain – plus you manage proxies and infrastructure yourself. The Web API does that work for you: one simple API handles JavaScript rendering, proxy rotation, and delivery, returning clean data in flexible formats like JSON, HTML, or Markdown. It's highly scalable by design, so you can scale data collection through API requests without building or maintaining the pipeline behind it.
Yes. Every request returns fresh, real-time data collected from live web pages that are gathered upon request, not pulled from a cached index. This makes it ideal for use cases where data must be current, such as AI workflows, monitoring, and research. Because it's built for data at scale, you get up-to-date public data on demand, delivered in the output formats your AI systems and data pipelines need.
Yes. Every new user gets a free trial with $5 in credits and no time limit – enough to test the Web API's Search and Scrape endpoints at your own pace.
Give agents the live web
One API for search and retrieval – start free, scale when you're ready.